Fake News Classifier
Designed and trained a bidirectional LSTM neural network on a labelled Pakistani news dataset achieving 97.5% classification accuracy — distinguishing real journalism from fabricated misinformation.
Background & Objective
The rapid proliferation of fake news represents one of the defining information challenges of the digital era. Fabricated articles — particularly in politically sensitive contexts — can manipulate public opinion, undermine democratic processes, and incite real-world harm. Automated detection methods are therefore of enormous practical and societal importance.
This project builds a full end-to-end deep learning pipeline to classify news articles as real or fake. The training corpus is drawn from Pakistani political journalism (650 verified real articles + 286 labelled fake articles), making the problem both linguistically specific and topically rich. The final LSTM model achieves 97.5% test accuracy.
Dataset & Exploratory Analysis
Data Sources
Two CSV datasets were ingested: 650 real news dataset.csv (653 verified real news rows, 18 features) and 286 fake news dataset.csv (285 fake news rows, 18 features). Features include headline, body text, author, publication date, source URL, party affiliation, subject, and regional metadata.
Label Engineering
Binary labels were assigned: Label = 1 for real news and Label = 0 for fake news. The datasets were then vertically concatenated into a unified 938-row corpus and shuffled to prevent order bias.
Word Cloud Visualisation
Word clouds were generated separately for fake and real news bodies using WordCloud with custom stopwords. Dominant terms in fake news skewed toward sensational political actors (e.g., "PTI", "PMLN"), whereas real news showed richer journalistic vocabulary — confirming that language patterns alone encode label information.
Author & Source Distribution
Value-count analysis on the Author field revealed heavy concentration — Soch Fact Check (78 articles) and AFP (68) dominate the fake news corpus. CountVectorizer was used for bigram frequency analysis to expose phrasing patterns specific to each class.
Model Architecture & Training Pipeline
1. Text Preprocessing & Tokenisation
Raw text was cleaned by stripping punctuation and lowercasing. Keras Tokenizer fitted on the training set with a vocabulary ceiling of the top-N tokens. Sequences were zero-padded to a uniform length using pad_sequences to form the input tensor.
2. Train / Test Split
Scikit-learn's train_test_split partitioned the corpus into 80% training (758 rows) and 20% test (80 rows). Stratification preserved the class ratio across splits, ensuring unbiased evaluation.
3. LSTM Neural Network
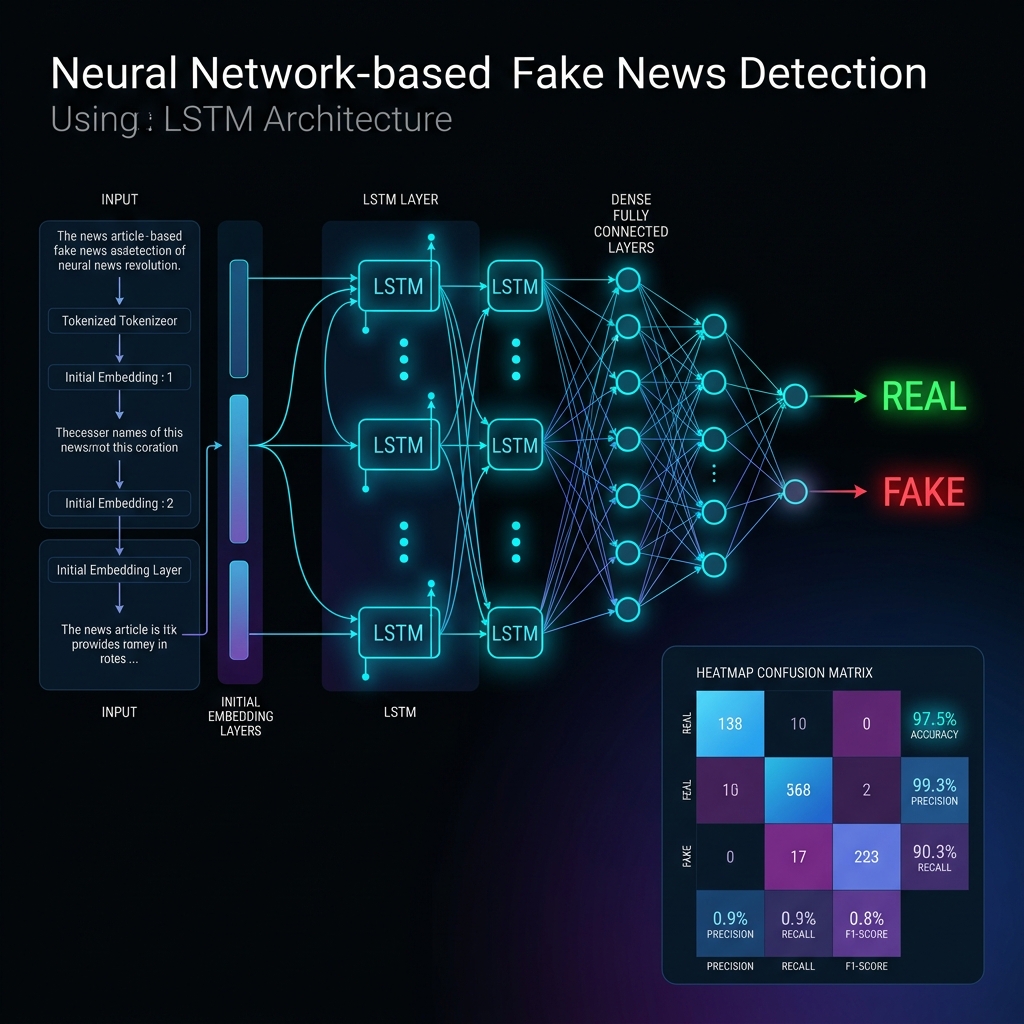
A Sequential Keras model was constructed with: (i) an Embedding layer mapping token indices to dense 128-dimensional vectors; (ii) a SpatialDropout1D regularisation layer; (iii) an LSTM layer capturing long-range sequential dependencies in the text; and (iv) a final Dense(2, softmax) classification head. The model was compiled with categorical_crossentropy loss and trained for 10 epochs with batch size 128.
4. Training Dynamics
Training accuracy reached 100% by epoch 6, with validation accuracy stabilising at 97.5–98.75%. The training loss curve showed rapid convergence; validation loss exhibited minor overfitting after epoch 2, consistent with the small dataset size. Loss and accuracy curves were plotted with matplotlib to verify stable learning.
Evaluation & Results
The confusion matrix (seaborn heatmap) confirmed only 2 misclassifications out of 80 test samples — both false negatives (fake articles predicted as real). The classification report showed precision of 1.00 for the fake class (zero false positives) and recall of 0.88, with weighted averages of precision 0.98, recall 0.97, F1 0.97. The high precision for fake news is particularly valuable in deployment scenarios where false alarms carry reputational cost.
Tech Stack
Model Stats
- Architecture LSTM
- Training Epochs 10
- Batch Size 128
- Classes Real / Fake
- Test Samples 80